·824 words·4 mins
Training a small transformer to generate 16x16 pixel art characters by de-masking pixels step by step.
·1082 words·6 mins
A simple MLP on MNIST to see how batch, layer, and group normalization differ in training speed, accuracy, and neuron activations.
·1233 words·6 mins
Building a discrete diffusion transformer (DiT) from scratch and training it to generate Shakespeare-like text, one denoising jump at a time.
·823 words·4 mins
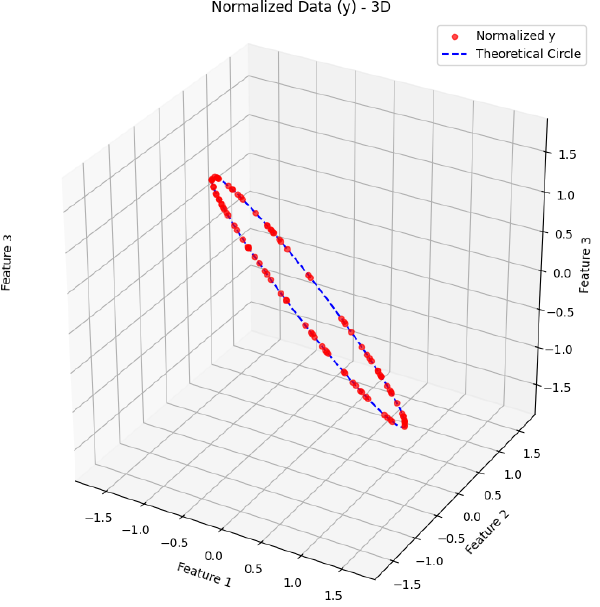
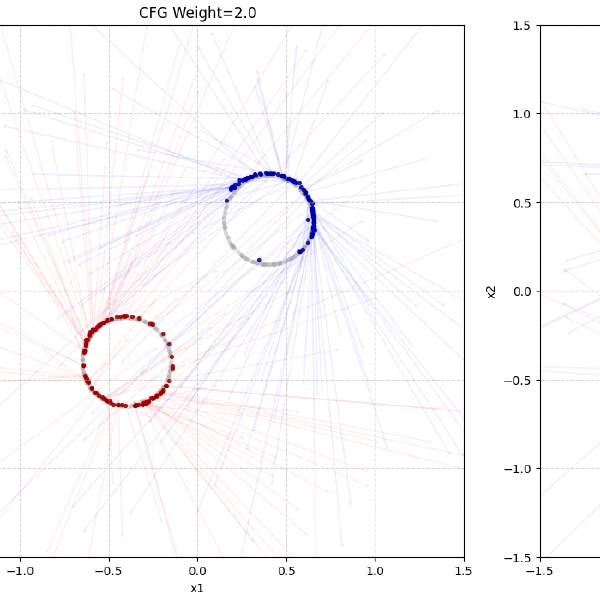
A follow-up to the 2-D diffusion notebook: steering generation with labels, from vanilla conditioning to classifier-free guidance.
·1160 words·6 mins
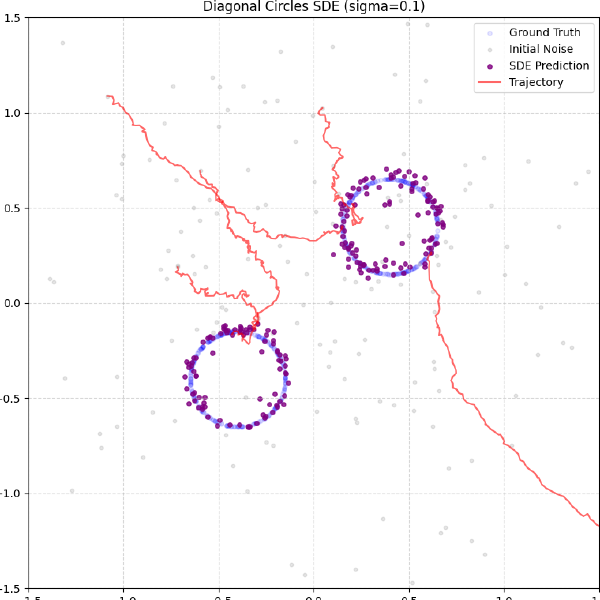
A trimmed, annotated companion to the 2-D diffusion notebook — with an ODE-vs-SDE sampling comparison.